K-Dense BYOK on CompBioBench: Three Models, One Harness
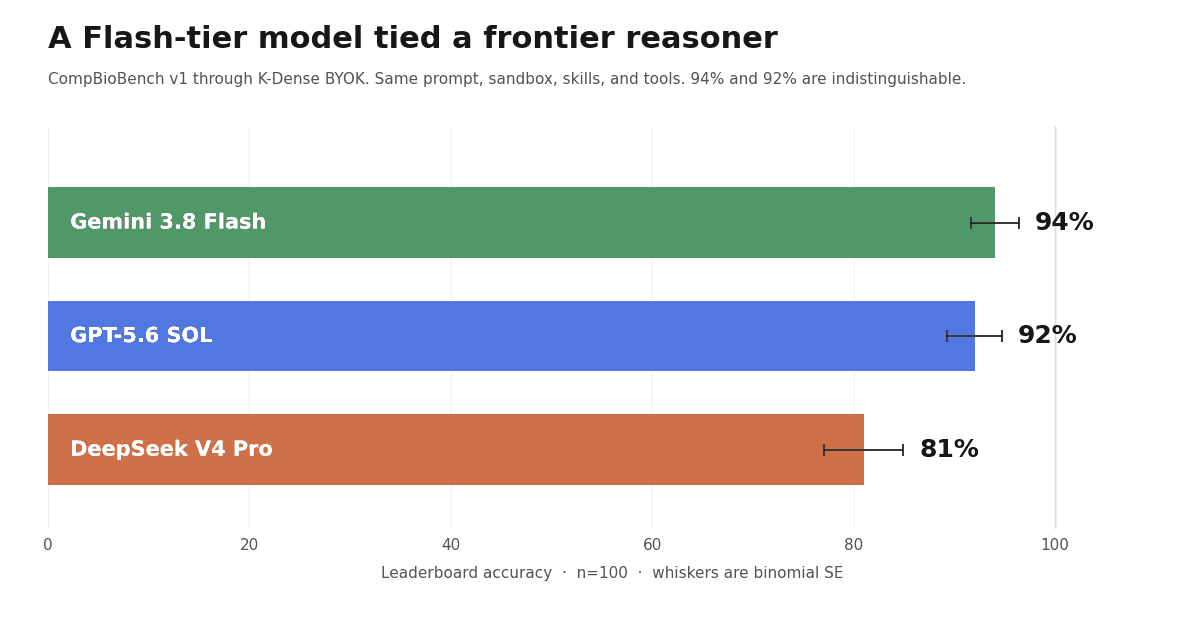
Gemini 3.8 Flash scored 94% and GPT-5.6 SOL 92% on CompBioBench v1, a statistical tie. DeepSeek V4 Pro scored 81% on the same K-Dense BYOK harness (n=100).
16 min read
Topic
12 K-Dense articles on Benchmarks — research automation, benchmarks, and case studies from the K-Dense team.
Gemini 3.8 Flash scored 94% and GPT-5.6 SOL 92% on CompBioBench v1, a statistical tie. DeepSeek V4 Pro scored 81% on the same K-Dense BYOK harness (n=100).
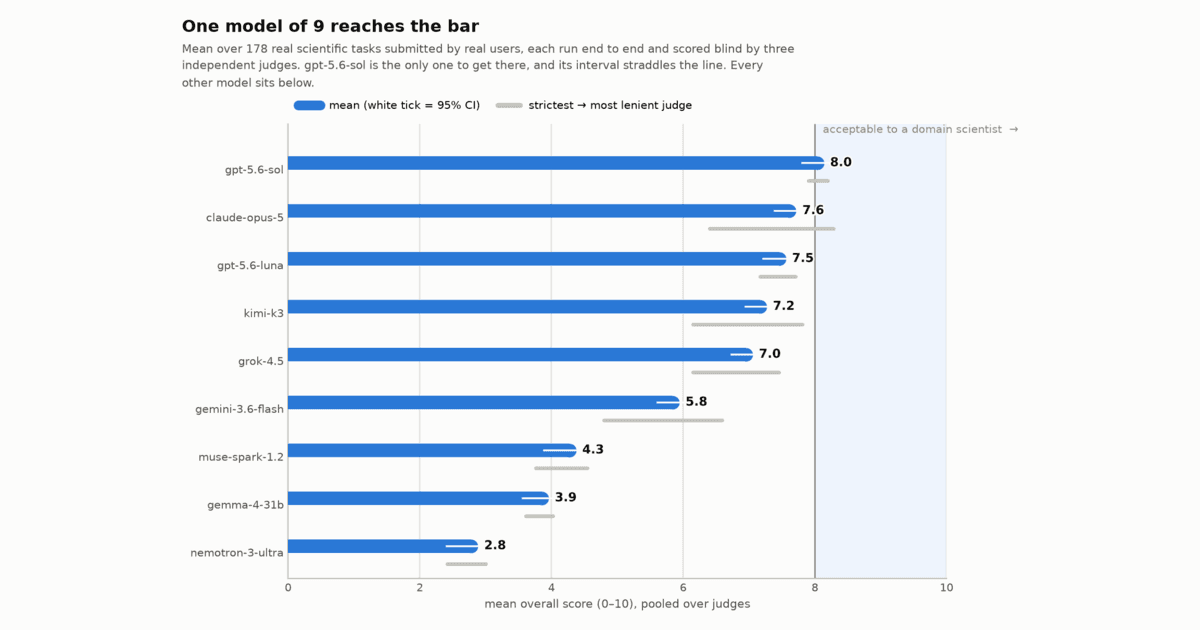
K-Bench 01 is our internal benchmark built from 178 real scientific tasks. Nine frontier models ran them end to end; only one clears the acceptability bar.
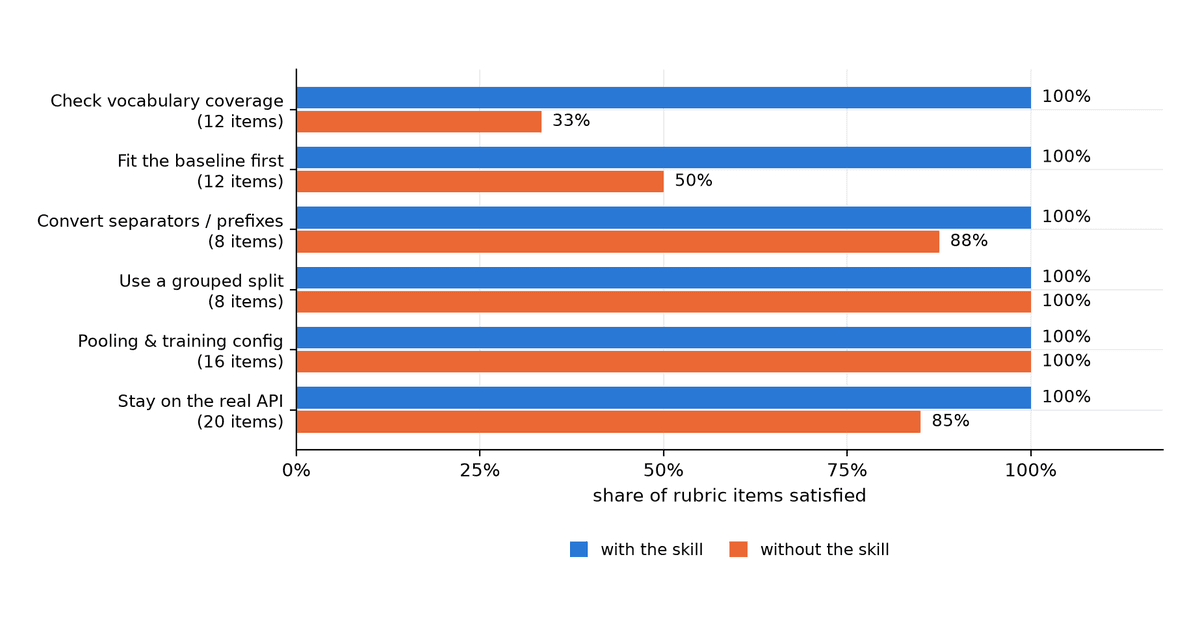
A microbiome foundation model silently discards 97% of a malformed table and returns a valid embedding. We measured what an Agent Skill does about that.
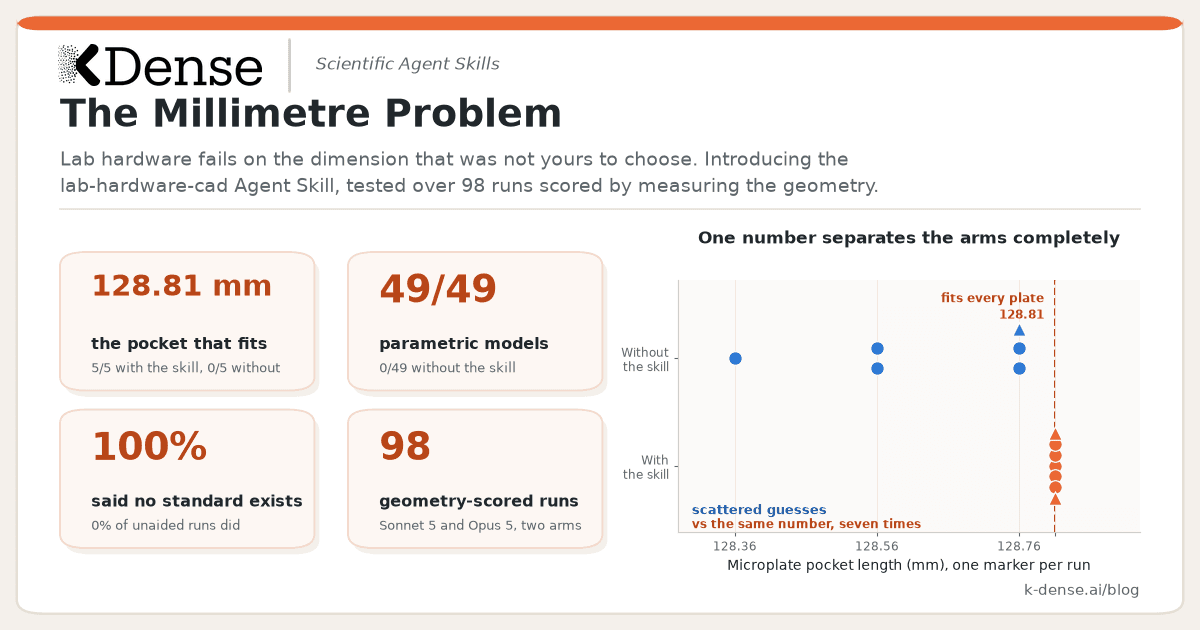
Introducing lab-hardware-cad, an open-source Agent Skill that turns any AI agent into a CAD engineer for lab hardware, benchmarked over 98 geometry-scored runs.
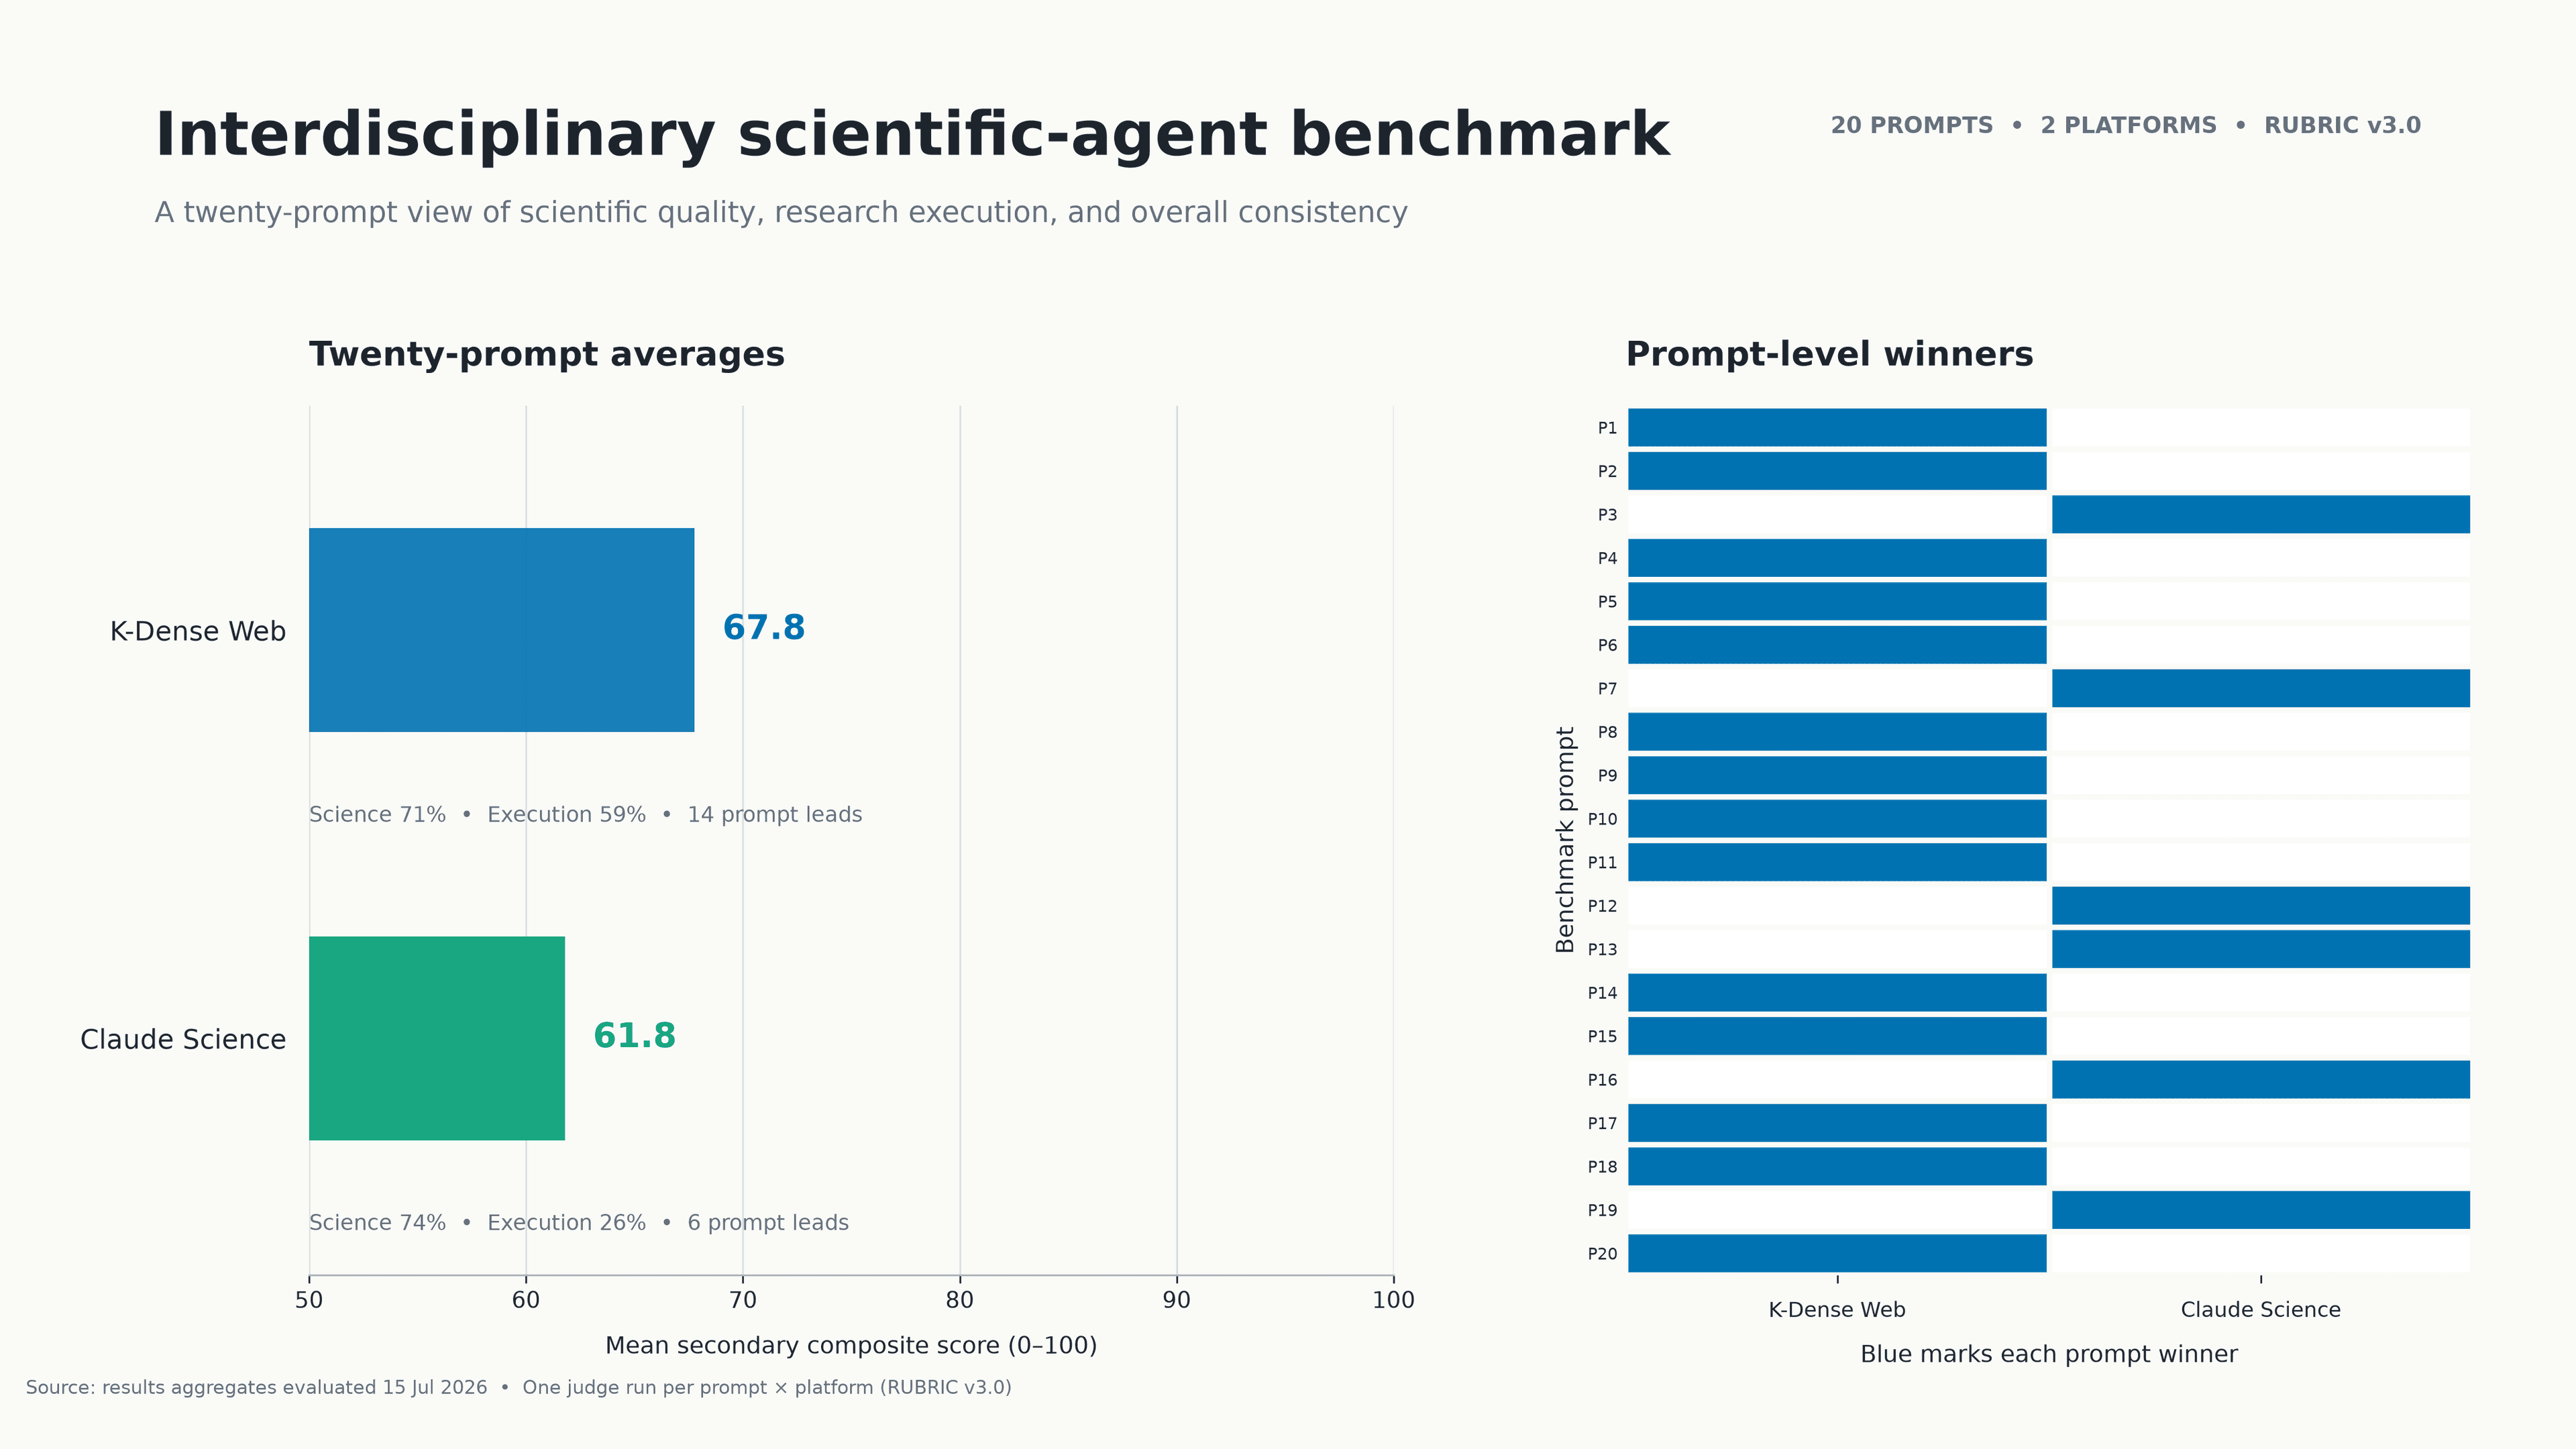
A 20-task benchmark found K-Dense Web stronger at producing auditable research bundles, while Claude Science held a narrow scientific-quality lead.
A 35-case K-Dense benchmark of Google's Omni Flash shows stunning scientific video quality, but unreliable text, physics, and factual correctness.
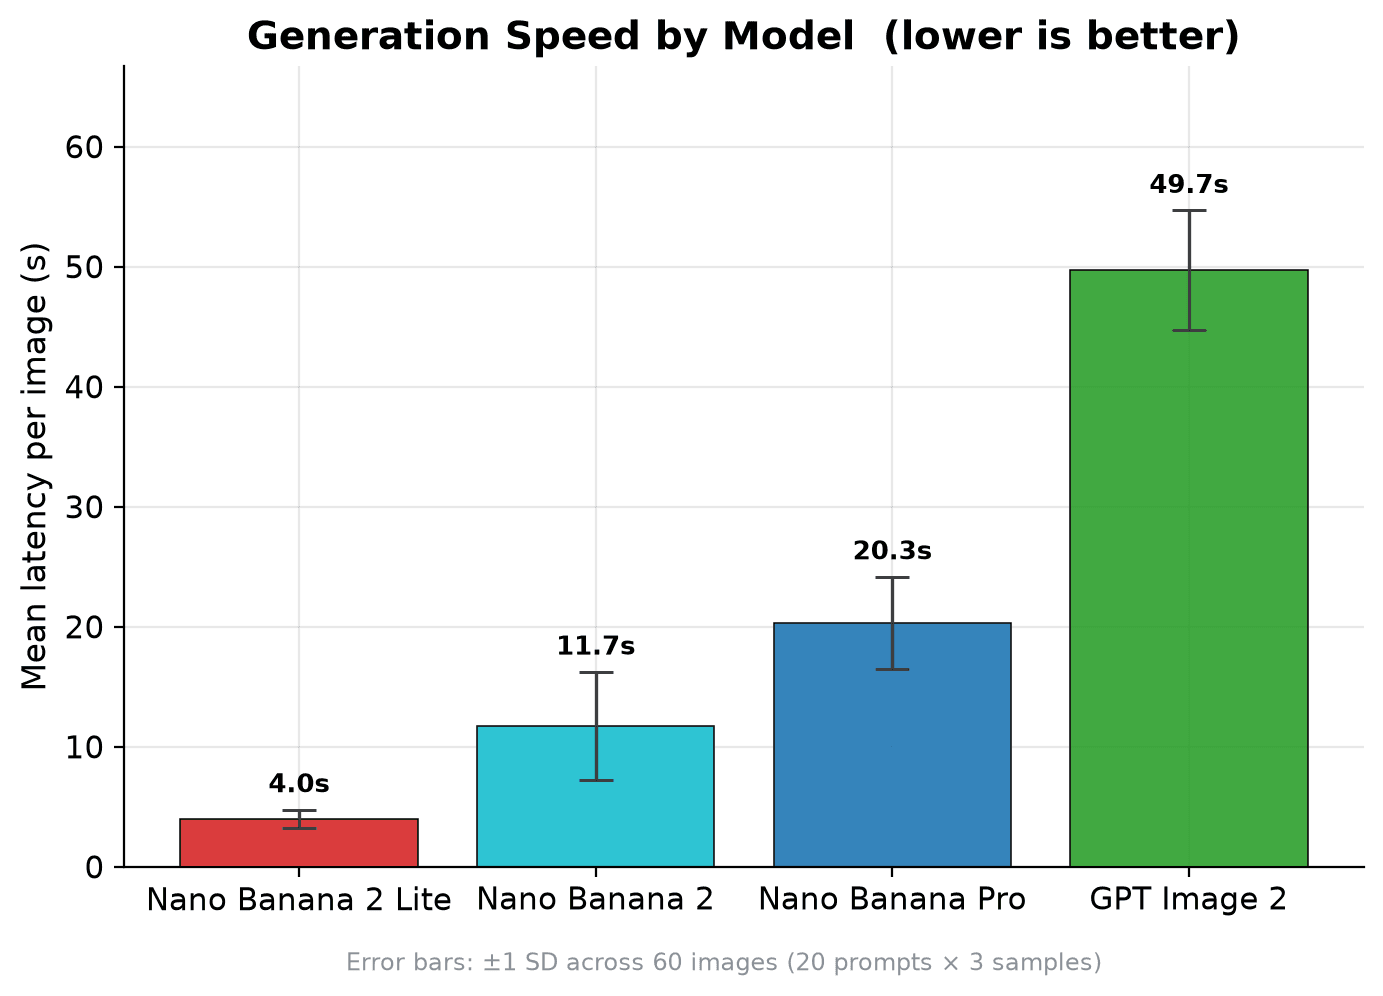
A 240-image benchmark of four scientific image models shows Nano Banana 2 Lite is fastest, while GPT Image 2 still leads on raw figure quality.
The next AI scientist benchmark should be a lab escape room: a fresh hidden world, limited probes, real evidence, and no place for science theater to hide.
AI is flooding science with claims no one can check. The quieter story: agents now reproduce most published findings — and that is the bigger deal.
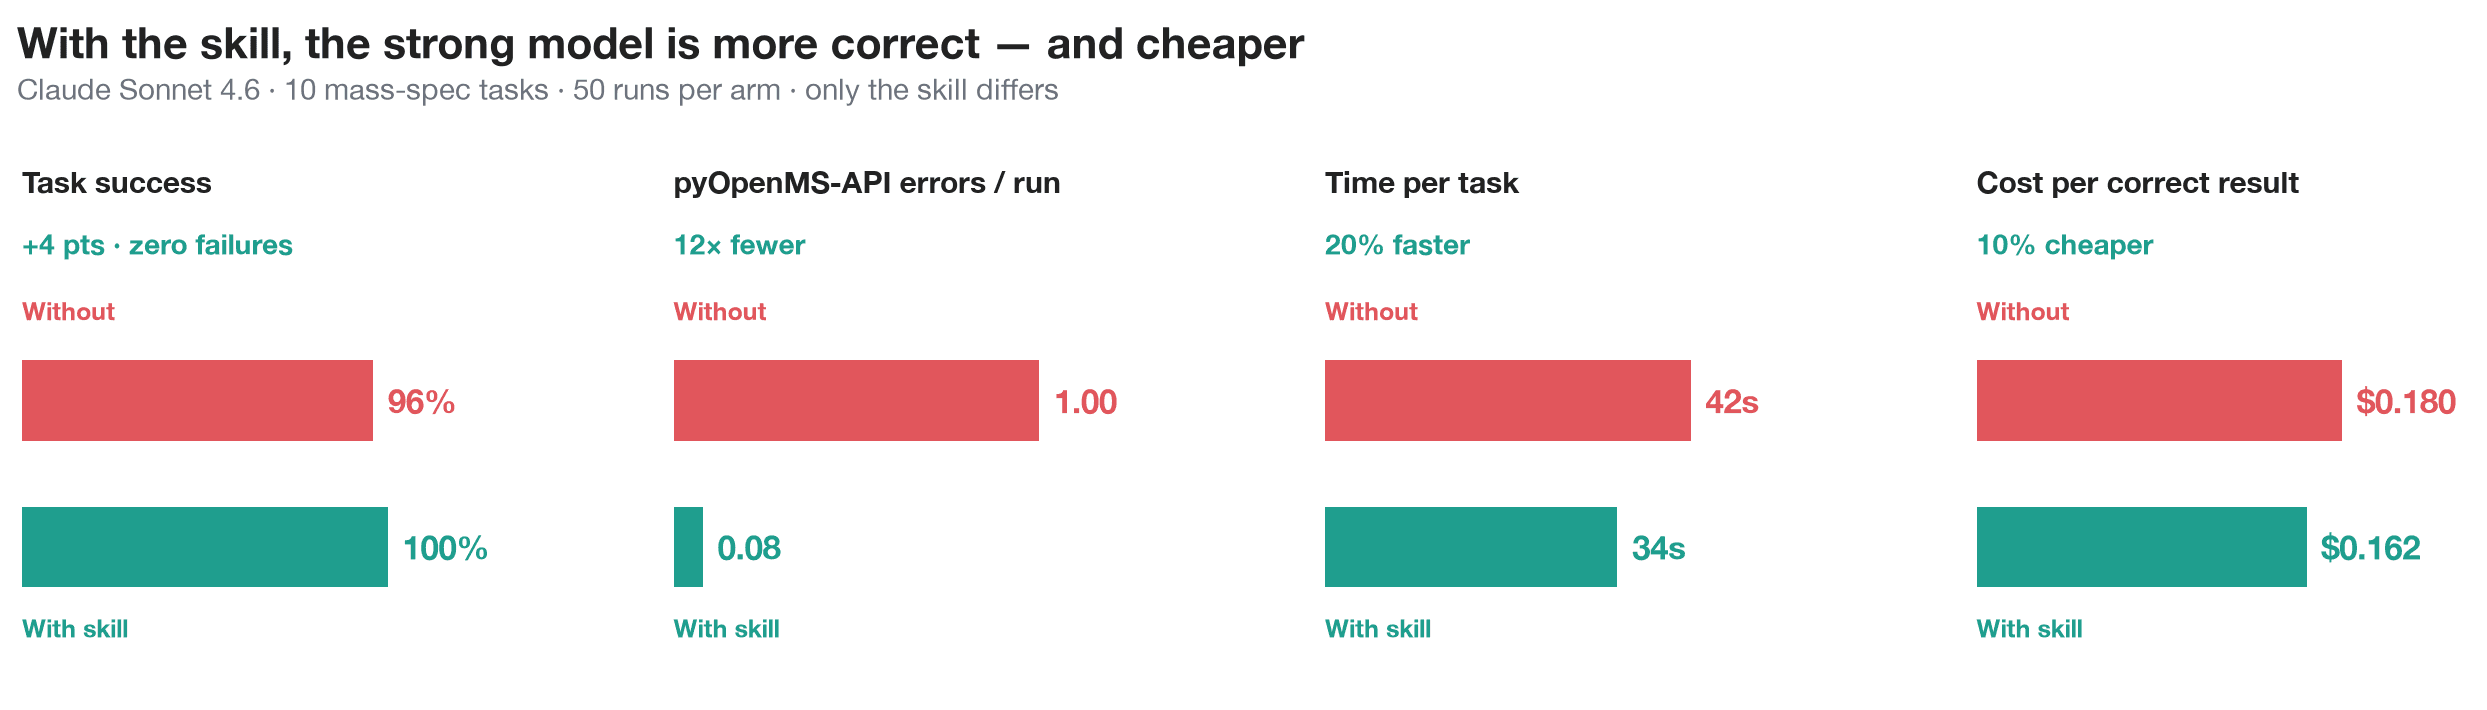
A reproducible 250-run study of feature detection, adduct grouping, quantification, and identification, run by an AI agent with and without the pyOpenMS skill.
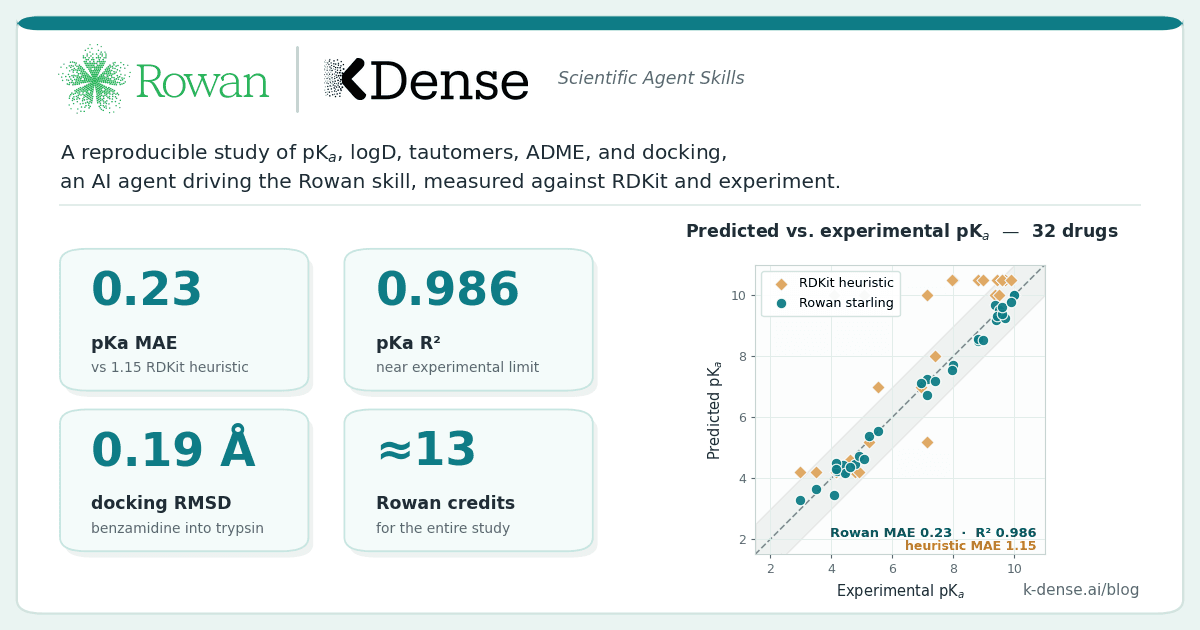
A reproducible study of pKa, logD, tautomers, ADME, and docking run by an AI agent with the Rowan skill, measured against RDKit and experimental ground truth.
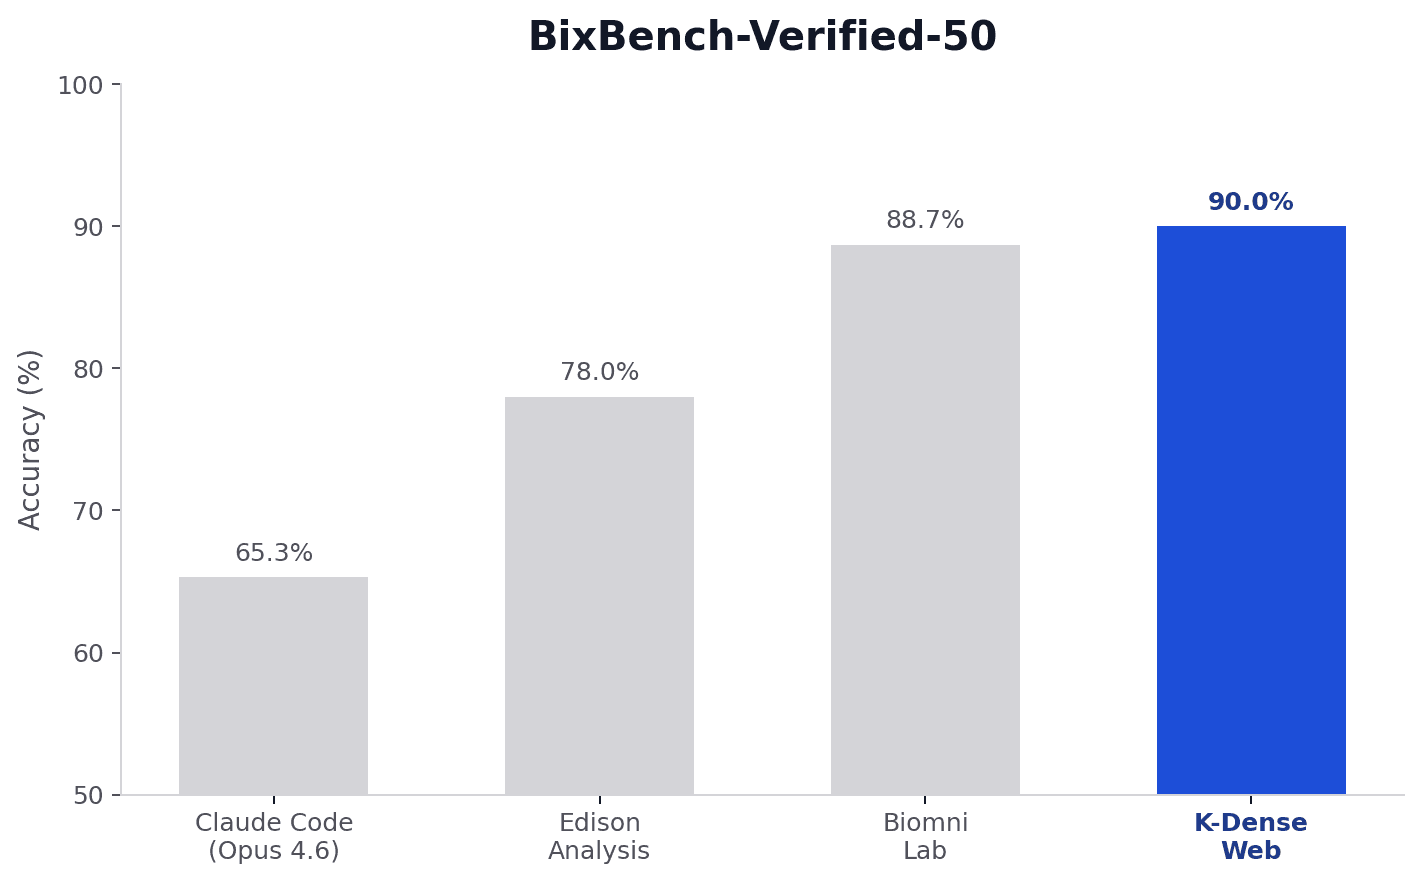
K-Dense Web scored 45/50 on BixBench-Verified-50, a cleaned biology-agent benchmark designed to separate real model mistakes from benchmark noise.